

Section 05
55. A Socio-Technical Pipeline for Enterprise AI
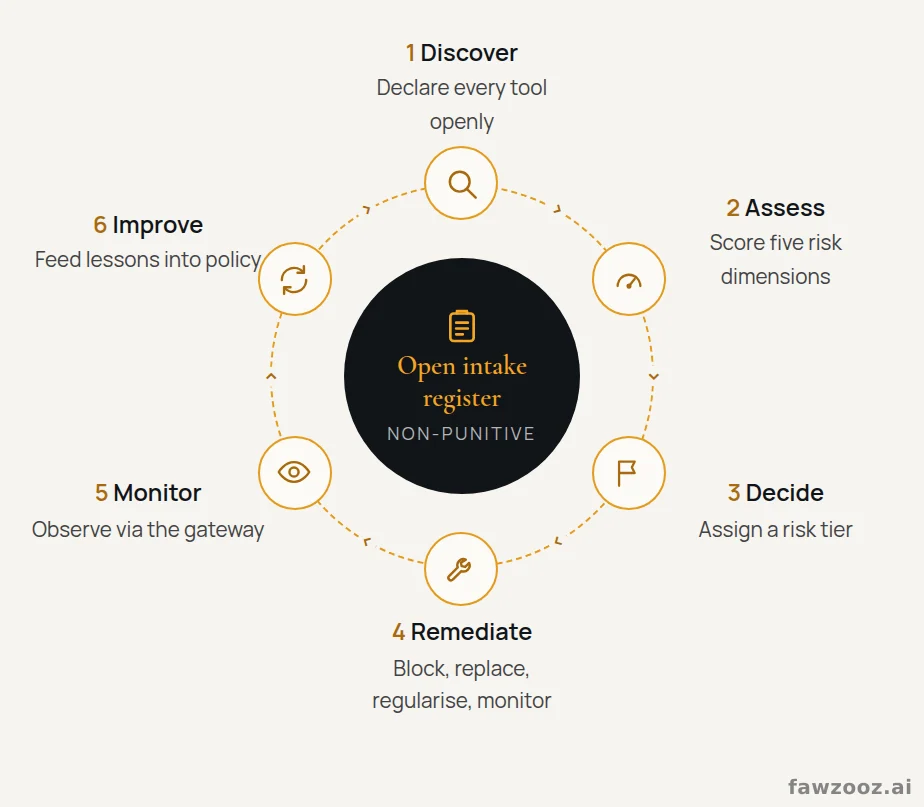
The first task is to remove the incentive to hide. An open, non-punitive intake register becomes the operational core of a six-stage lifecycle: Discover, Assess, Decide, Remediate, Monitor and Improve.
Text in this figure
Open intake register · NON-PUNITIVE · › · › · › · › · › · › · Discover · 1 · Declare every tool openly · Assess · 2 · Score five risk dimensions · Decide · 3 · Assign a risk tier · Remediate · 4 · Block, replace, regularise, monitor · Monitor · 5 · Observe via the gateway · Improve · 6 · Feed lessons into policy · Figure 7. The six-stage shadow AI lifecycle, anchored on the open intake register.
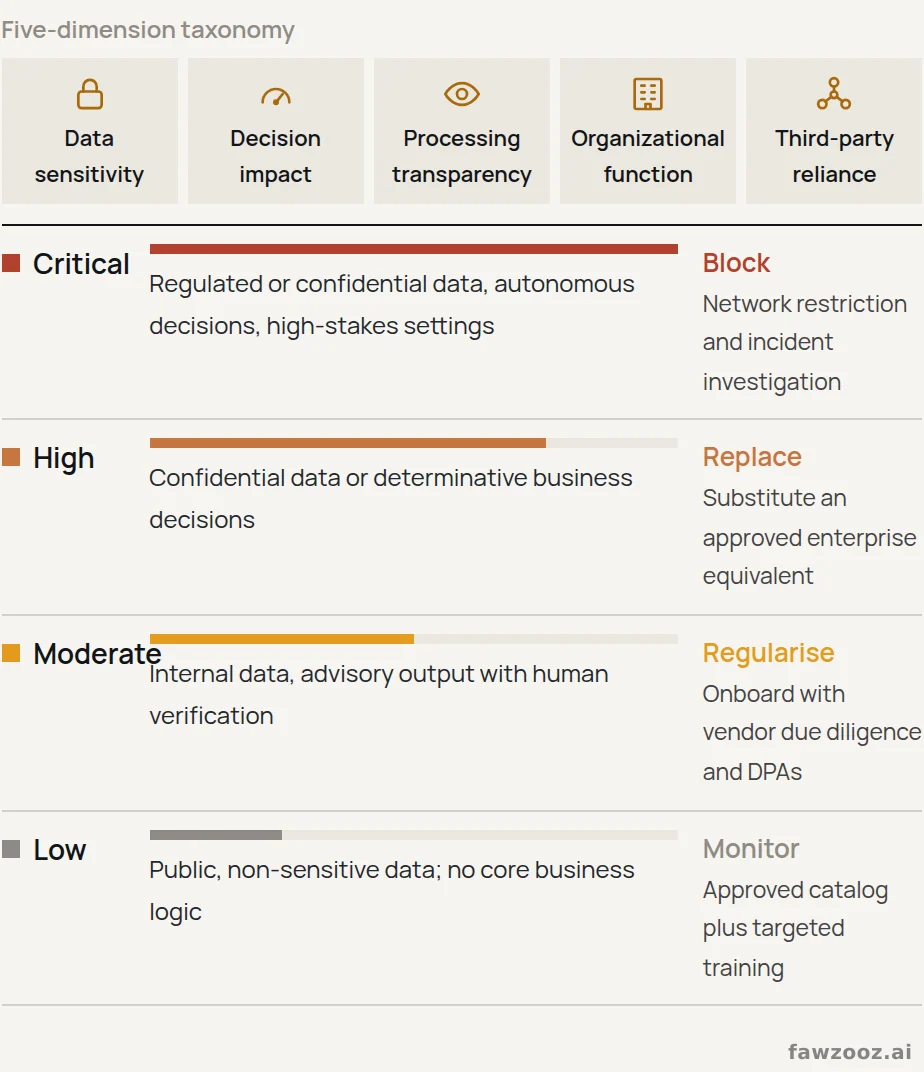
During Discover and Assess, every declared instance is scored on a five-dimensional taxonomy — data sensitivity, decision impact, processing transparency, organizational function and third-party supply-chain reliance — and placed in one of four risk tiers, each with a mandatory remediation pathway.
Text in this figure
Five-dimension taxonomy · Data sensitivity · Decision impact · Processing transparency · Organizational function · Third-party reliance · Critical · Regulated or confidential data, autonomous decisions, high-stakes settings · Block · Network restriction and incident investigation · High · Confidential data or determinative business decisions · Replace · Substitute an approved enterprise equivalent · Moderate · Internal data, advisory output with human verification · Regularise · Onboard with vendor due diligence and DPAs · Low · Public, non-sensitive data; no core business logic · Monitor · Approved catalog plus targeted training · Figure 8. Risk tier classification and remediation pathways. Aligned with NIST AI RMF and ISO/IEC 42001.
5.1 The Enterprise AI Gateway within SASE
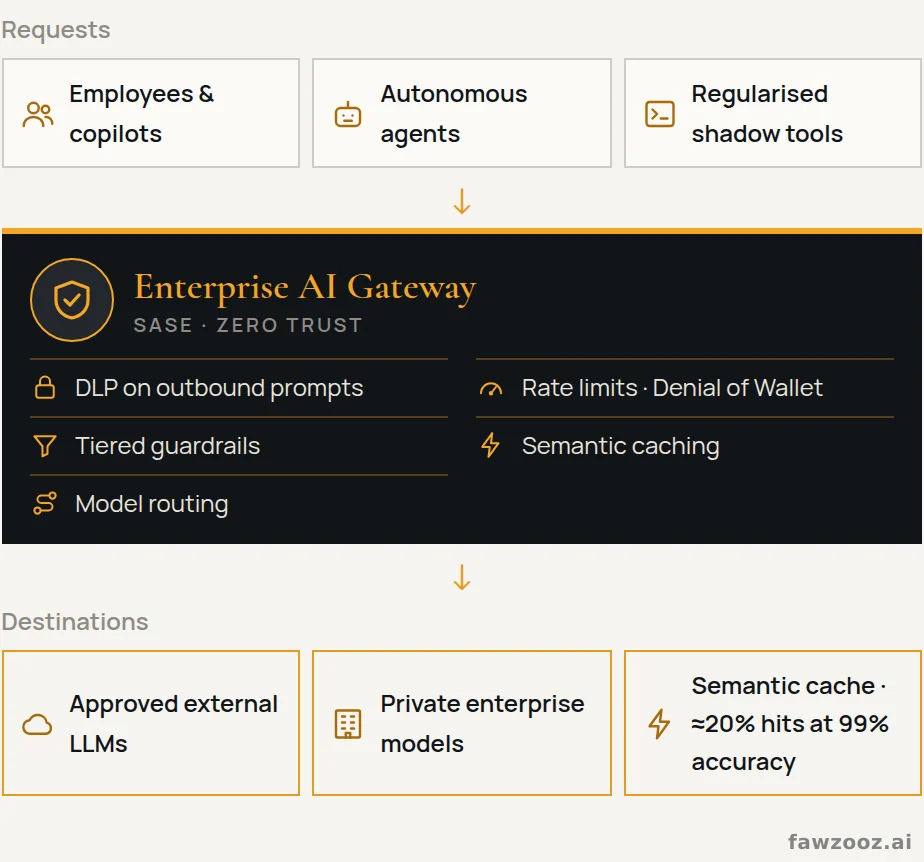
Once approved, ad-hoc connections are restructured so that all traffic flows through a unified Enterprise AI Gateway integrated within a Secure Access Service Edge (SASE) and Zero Trust architecture. The gateway is a mandatory orchestration proxy: it applies custom DLP policies to outbound prompts, enforces rate limits against ‘Denial of Wallet’ attacks, and manages model routing.
The gateway also enables semantic caching. Unlike exact-match caching, it uses vector databases to recognize linguistic equivalence — matching ‘What is our Q3 revenue?’ with ‘Show me third-quarter earnings’ — yielding cache hit rates reported by vendors at around 20% with high match accuracy (indicative, workload-dependent), sharply reducing cost and latency.
Text in this figure
Requests · Employees & copilots · Autonomous agents · Regularised shadow tools · ↓ · Enterprise AI Gateway · SASE · ZERO TRUST · DLP on outbound prompts · Rate limits · Denial of Wallet · Tiered guardrails · Semantic caching · Model routing · ↓ · Destinations · Approved external LLMs · Private enterprise models · Semantic cache · ≈20% hits at 99% accuracy · Figure 9. Every AI request passes through a single SASE-integrated gateway before reaching any model.
5.2 Tiered Cognitive Guardrails
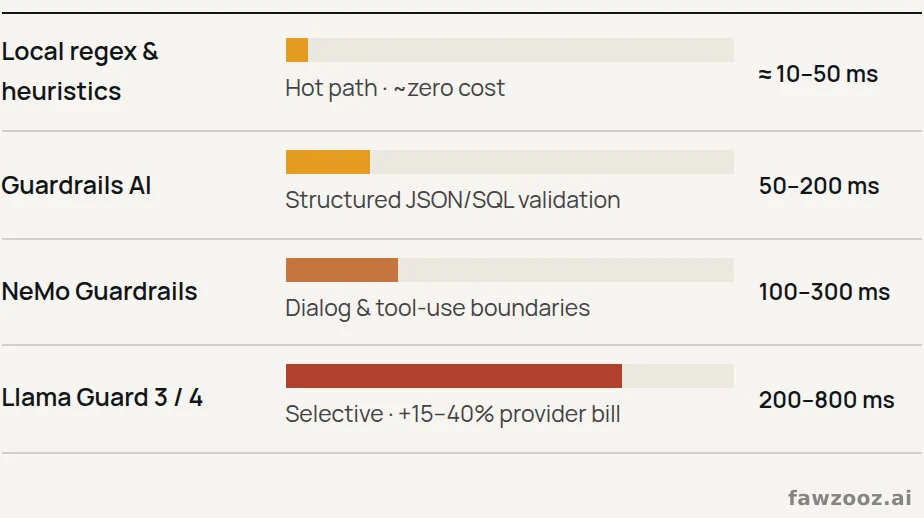
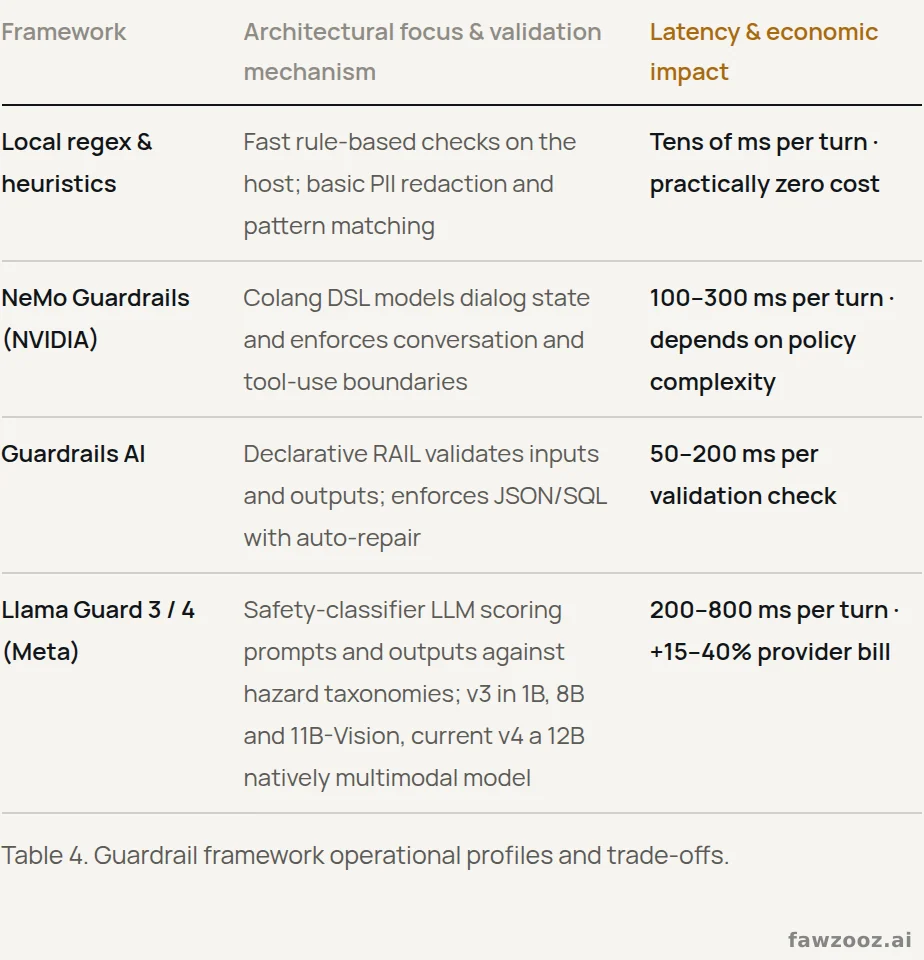
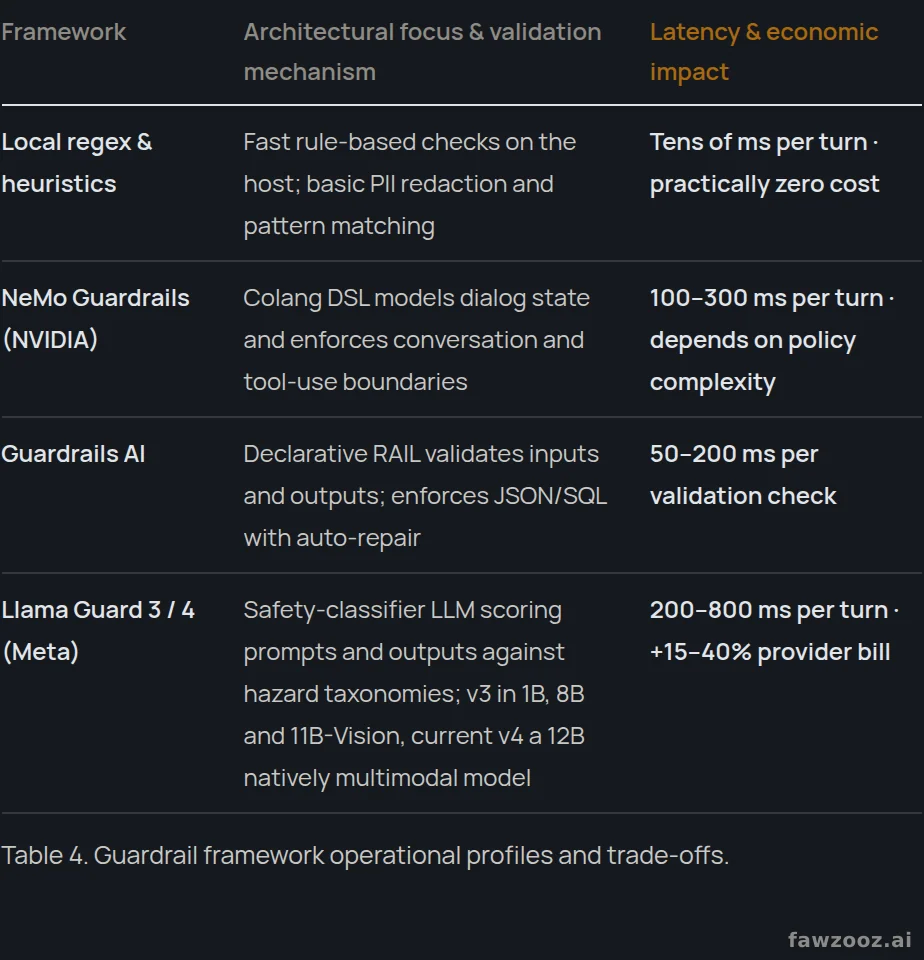
Static firewalls cannot secure probabilistic outputs. Gateways must deploy dynamic guardrails that validate inputs, manage dialog and screen outputs — but every guardrail trades safety against latency and cost.
Text in this figure
Local regex & heuristics · Hot path · ~zero cost · ≈ 10–50 ms · Guardrails AI · Structured JSON/SQL validation · 50–200 ms · NeMo Guardrails · Dialog & tool-use boundaries · 100–300 ms · Llama Guard 3 / 4 · Selective · +15–40% provider bill · 200–800 ms · Figure 10. Latency overhead per turn by guardrail framework. Indicative figures compiled from vendor documentation and published guardrail benchmarks; actual latency varies by model, hardware and payload.
Text in this figure
Framework · Architectural focus & validation mechanism · Latency & economic impact · Local regex & heuristics · Fast rule-based checks on the host; basic PII redaction and pattern matching · Tens of ms per turn · practically zero cost · NeMo Guardrails (NVIDIA) · Colang DSL models dialog state and enforces conversation and tool-use boundaries · 100–300 ms per turn · depends on policy complexity · Guardrails AI · Declarative RAIL validates inputs and outputs; enforces JSON/SQL with auto-repair · 50–200 ms per validation check · Llama Guard 3 / 4 (Meta) · Safety-classifier LLM scoring prompts and outputs against hazard taxonomies; v3 in 1B, 8B and 11B-Vision, current v4 a 12B natively multimodal model · 200–800 ms per turn · +15–40% provider bill · Table 4. Guardrail framework operational profiles and trade-offs.
Relying solely on LLM-as-a-judge classifiers creates latency bottlenecks, and on novel adversarial injections their capture rates can fall to an estimated 60–85% while flagging an estimated 5–15% of legitimate requests. The optimal pattern is tiered: cheap local validators on the hot path for every transaction, with expensive cognitive classifiers invoked only for ambiguous inputs or untrusted external data.
5.3 Agile LLMOps
Gateway-routed tools then enter an agile LLMOps framework in which prompts are managed as immutable, versioned code. Evaluation tools such as RAGAS (RAG faithfulness and contextual relevance) and DeepEval (LLM-as-a-judge quality gates) are embedded in CI/CD to catch regression and model drift before production.
Tip: use ← → to move between sections.